All categories Paiton (33) Artificial Intelligence (28) AMD (13) vLLM (10) AMD Radeon (7) NVidia (7) Solutions (7) AI (6) H200 (6) MI300X (6) AMD MI300X (5) Inference Optimization (5) Modular DC (5) Trending (5) AI Inference (4) AI Infrastructure (4) Local AI (4) MI325x (4) Sovereign AI (4) Agentic AI (3) B200 (3) Cost Efficiency (3) Generative AI (3) GPU Performance (3) H100 (3) Inference Latency (3) Large Language Models (3) Local LLM (3) On-Premise AI (3) ComfyUI (2) Cybersecurity (2) Damage Detection (2) Deepseek (2) Document Processing (2) Eliovp (2) Email Automation (2) Enterprise AI (2) FP8 (2) GDPR (2) GPU (2) High Density (2) HPC (2) Image Generation (2) Invoice Extraction (2) Kernel Tuning (2) Liquid Cooling (2) Llama 3.1 405B (2) MI355x (2) Modular Data Center (2) NVL72 (2) Privacy (2) Ticket Automation (2) Workflow Automation (2) 1-2MW Data Center (1) 14B (1) 150kW Rack (1) AI Act (1) AI Agents (1) AI Benchmarks (1) AI Engineering (1) AI Neocloud (1) AI news (1) AI Strategy (1) AMD Helios (1) AMD Instinct (1) Anthropomorphism (1) Autonomous Agents (1) AVG (1) AWS (1) Belgian Mobile ID (1) benchmark (1) Benchmarks (1) Benelux (1) Blackwell (1) ChatGPT (1) Circular Financing (1) Cloud Act (1) Cold Start (1) Cold Start Optimization (1) Compute (1) Cost per Token (1) CUDA Translation (1) Data Centers (1) Data Governance (1) Data Security (1) Data Sovereignty (1) De Tijd (1) DFlash2 (1) Diffusion (1) Digital Identity (1) DLC (1) eIDAS (1) ERP (1) FLUX (1) GGUF (1) GPU Cloud (1) GPU Optimization (1) Graph Compilation (1) Hardware (1) Healthcare (1) High Performance Computing (1) High Throughput (1) HIP (1) import (1) Inference (1) Instinct (1) Investment Risks (1) itsme (1) Jim Greene (1) Liberty Global (1) LLM (1) LLM Optimization (1) MI300 (1) Microsoft Copilot (1) MiniMax H3 (1) Mixture of Experts (1) Model Fine-Tuning (1) Model Serving (1) ModFlex (1) MoE (1) MyGov.be (1) NVIDIA B200 (1) NVIDIA Blackwell (1) NVIDIA Blackwell Ultra (1) NVIDIA GB300 (1) NVIDIA H200 (1) NVIDIA NVL (1) On-Premise (1) Optimization (1) pnl calculator (1) Podcast (1) Precision Cooling (1) Qwen (1) Qwen3 (1) Qwen3.8 (1) Rapid Deployment (1) ROCm (1) RX7900XTX (1) SGLang (1) Shadow AI (1) Startup Latency (1) Startup Valuation (1) Synthetic Bubble (1) T2V (1) Taiwan (1) Tariffs (1) Tech Analysis (1) Tech Talk (1) Tensor Parallelism (1) tenstorrent (1) Text-to-Video (1) Trump (1) Tuning (1) Vaporware (1) Venture Capital (1) Video Generation (1) Video-Generation (1) vLLM Optimization (1) VRAM Optimization (1) Wan2.2 (1)
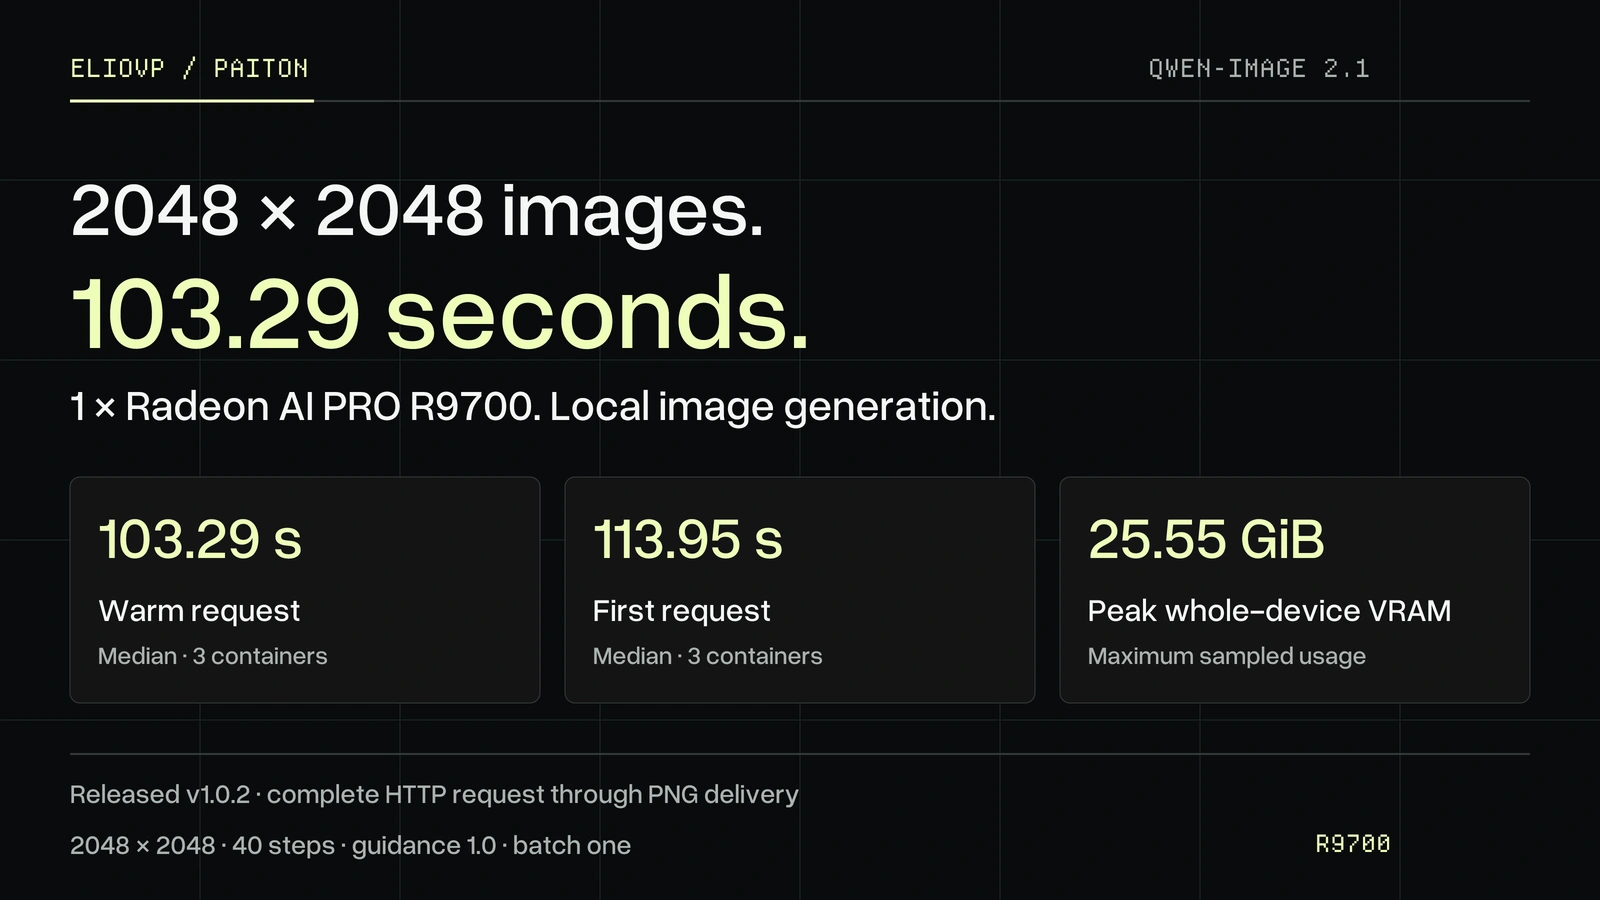
Qwen-Image 2.1 on 1 × Radeon AI PRO R9700: 2048×2048 images in 103 seconds Generate 2048×2048 Qwen-Image 2.1 images locally with 1 × Radeon AI PRO R9700. The released Paiton v1.0.2 container measured 103.29 seconds per warm request, through PNG delivery.
By: ElioVP
September 23, 2026
Paiton
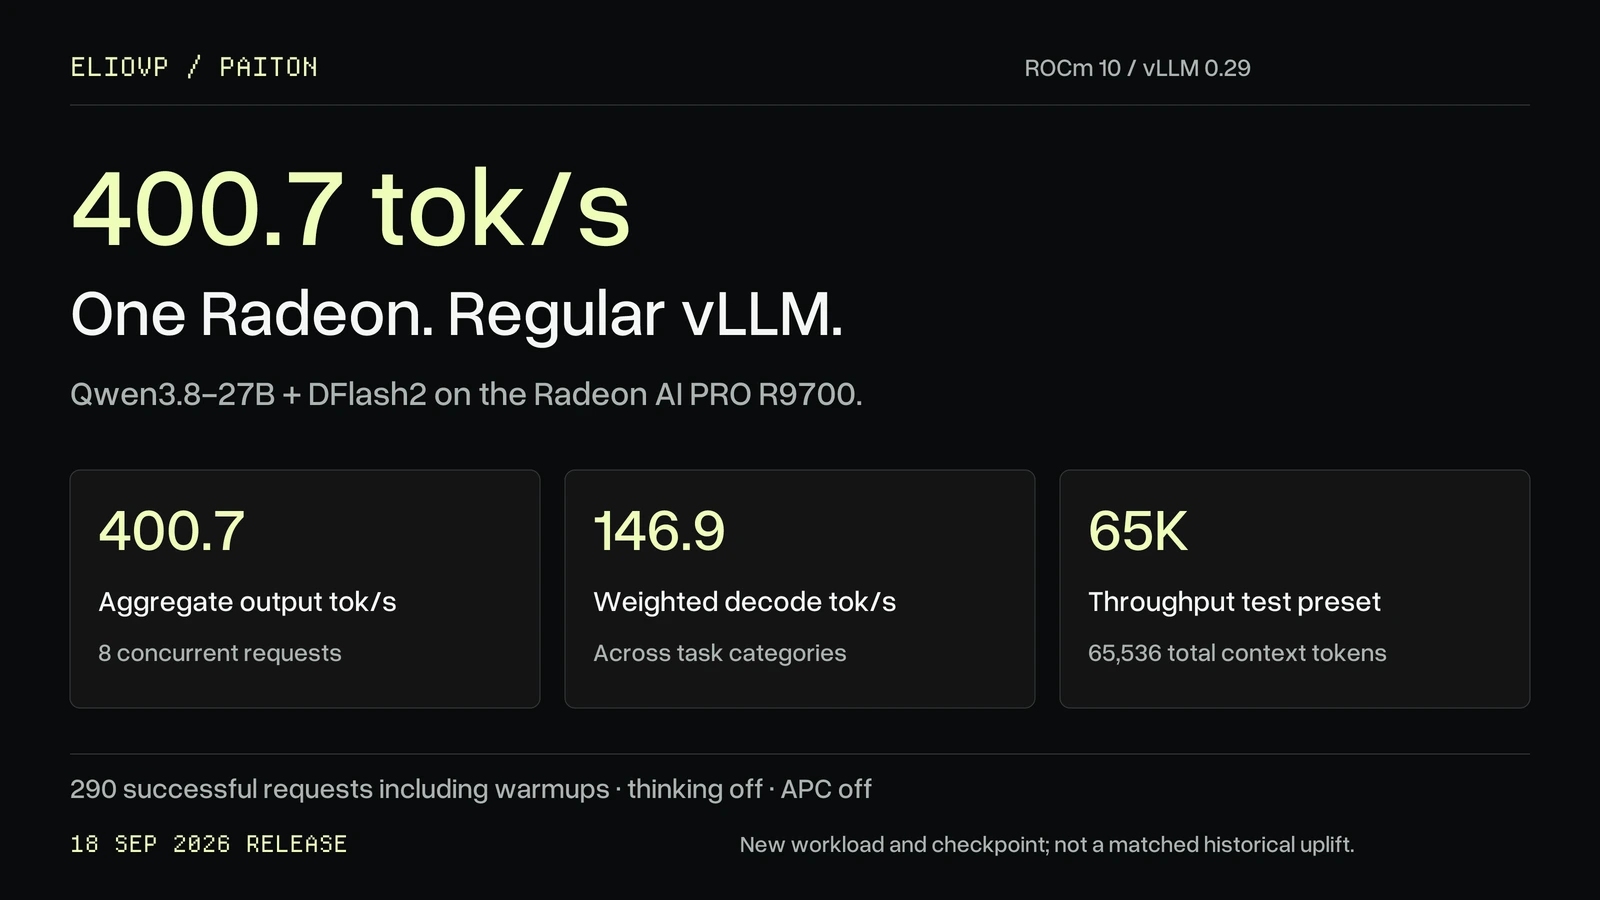
Qwen3.8: 400.7 tok/s on R9700 | Paiton Qwen3.8 on one R9700: 400.7 aggregate tok/s with ROCm 10 and vLLM 0.29, plus public 200K/220K chat profiles. Benchmarks, limits and launch commands.
By: ElioVP
September 16, 2026
Paiton
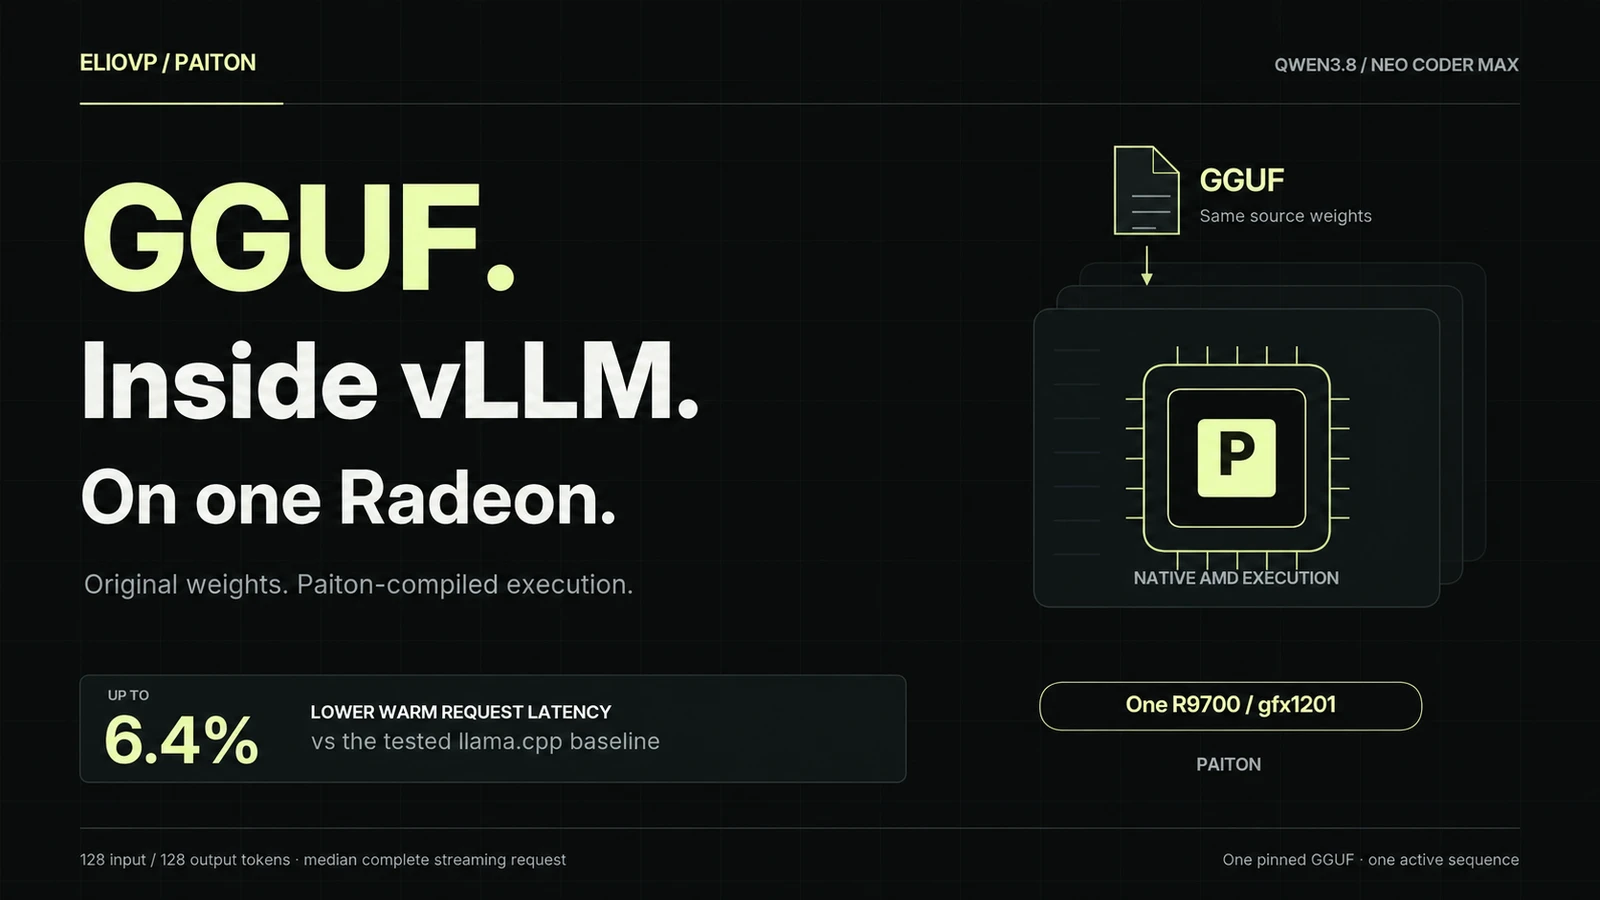
Qwen3.8 GGUF in vLLM: Faster Responses on One Radeon Run the original NEO CODER MAX GGUF in vLLM with Paiton on an R9700. Explore measured latency gains, image input and local deployment.
By: ElioVP
September 14, 2026
Paiton
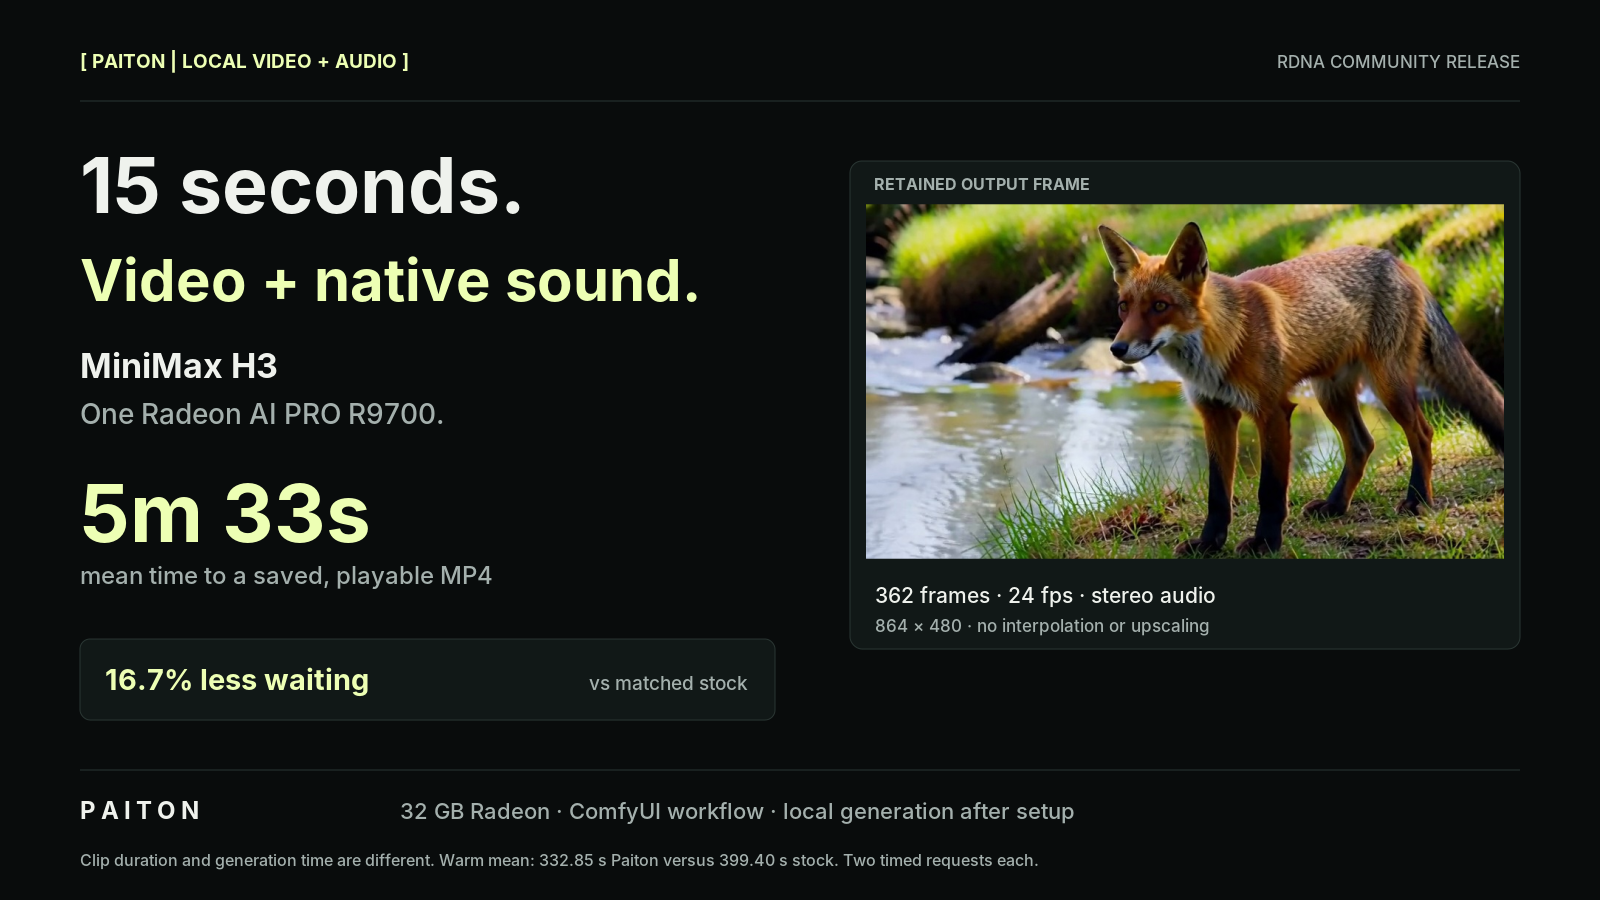
MiniMax H3 on Radeon: 15-Second Video With Native Sound Paiton generates a 15-second MiniMax H3 video with stereo audio on one Radeon AI PRO R9700 in 5m 33s, with 16.7% lower latency than matched stock.
By: ElioVP
September 9, 2026
Paiton
Local FLUX.2 klein on Radeon AI PRO R9700: Faster Image Generation with Less VRAM Paiton generates 1024×1024 FLUX.2 klein images in 1.054 seconds on an R9700: 16.2% lower warm latency and 33.4% lower peak Torch allocation.
By: ElioVP
September 7, 2026
Paiton