Alle categorieën Paiton (37) Kunstmatige intelligentie (28) AMD (13) AMD Radeon (11) vLLM (10) Lokale AI (9) NVIDIA (8) Oplossingen (7) AI (6) H200 (6) MI300X (6) AI-inferentie (5) AMD MI300X (5) Inferentie-optimalisatie (5) Modulaire DC (5) Qwen (5) Trending (5) Grote taalmodellen (4) Kwantisatie (4) MI325X (4) Soevereine AI (4) Agentic AI (3) AI op locatie (3) AI-infrastructuur (3) B200 (3) Generatieve AI (3) GPU-prestaties (3) H100 (3) Inferentielatentie (3) Kostenefficiëntie (3) Lokale LLM (3) Vloeistofkoeling (3) AI Infrastructure (2) Bedrijfs-AI (2) Beeldgeneratie (2) ComfyUI (2) Cyberbeveiliging (2) DeepSeek (2) Documentverwerking (2) E-mailautomatisering (2) Eliovp (2) Factuurextractie (2) FP8 (2) GDPR (2) GPU (2) Hoge dichtheid (2) HPC (2) Kerneltuning (2) Llama 3.1 405B (2) MI355x (2) ModFlex (2) Modulair datacenter (2) NVL72 (2) Privacy (2) Schadedetectie (2) Ticketautomatisering (2) Workflowautomatisering (2) 1-2MW datacenter (1) 14B (1) 150 kW-rack (1) AI Act (1) AI Neocloud (1) AI-agenten (1) AI-benchmarks (1) AI-nieuws (1) AI-strategie (1) AI-techniek (1) AMD Helios (1) AMD Instinct (1) Antropomorfisme (1) Autonome agenten (1) AVG (1) AWS (1) Beleggingsrisico's (1) Belgian Mobile ID (1) benchmark (1) Benchmarks (1) Benelux (1) Blackwell (1) ChatGPT (1) Circulaire financiering (1) CLOUD Act (1) Compute (1) CUDA-vertaling (1) Databeheer (1) Datacenters (1) Datasoevereiniteit (1) De Tijd (1) Diffusie (1) Digitale identiteit (1) DLC (1) Durfkapitaal (1) eIDAS (1) ERP (1) FLUX (1) Gegevensbeveiliging (1) GGUF (1) GPU Cloud (1) GPU-optimalisatie (1) Grafiekcompilatie (1) Hardware (1) High-performance computing (1) HIP (1) Hoge throughput (1) Inferentie (1) Instinct (1) Invoer (1) Invoerheffingen (1) itsme (1) Jim Greene (1) Kosten per token (1) Koude start (1) Koude startoptimalisatie (1) Liberty Global (1) LLM (1) LLM-optimalisatie (1) MI300 (1) Microsoft Copilot (1) MiniMax H3 (1) Mixture of Experts (1) Model serving (1) Modelverfijning (1) Modular DC (1) MoE (1) MyGov.be (1) NVIDIA B200 (1) NVIDIA Blackwell (1) NVIDIA Blackwell Ultra (1) NVIDIA GB300 (1) NVIDIA H200 (1) NVIDIA NVL (1) On-premises (1) Opstartlatentie (1) Opstartwaardering (1) Optimalisatie (1) P&L-calculator (1) Podcast (1) Precisiekoeling (1) Qwen3 (1) ROCm (1) RX7900XTX (1) SGLang (1) Shadow AI (1) Snelle implementatie (1) Synthetische bubbel (1) T2V (1) Taiwan (1) Tech Talk (1) Technische analyse (1) Tekst-naar-video (1) Tensor-parallellisme (1) tenstorrent (1) Trump (1) Tuning (1) Vaporware (1) Vera Rubin (1) Video-generatie (1) Videogeneratie (1) vLLM-optimalisatie (1) VRAM-optimalisatie (1) Wan2.2 (1) Zorg (1)
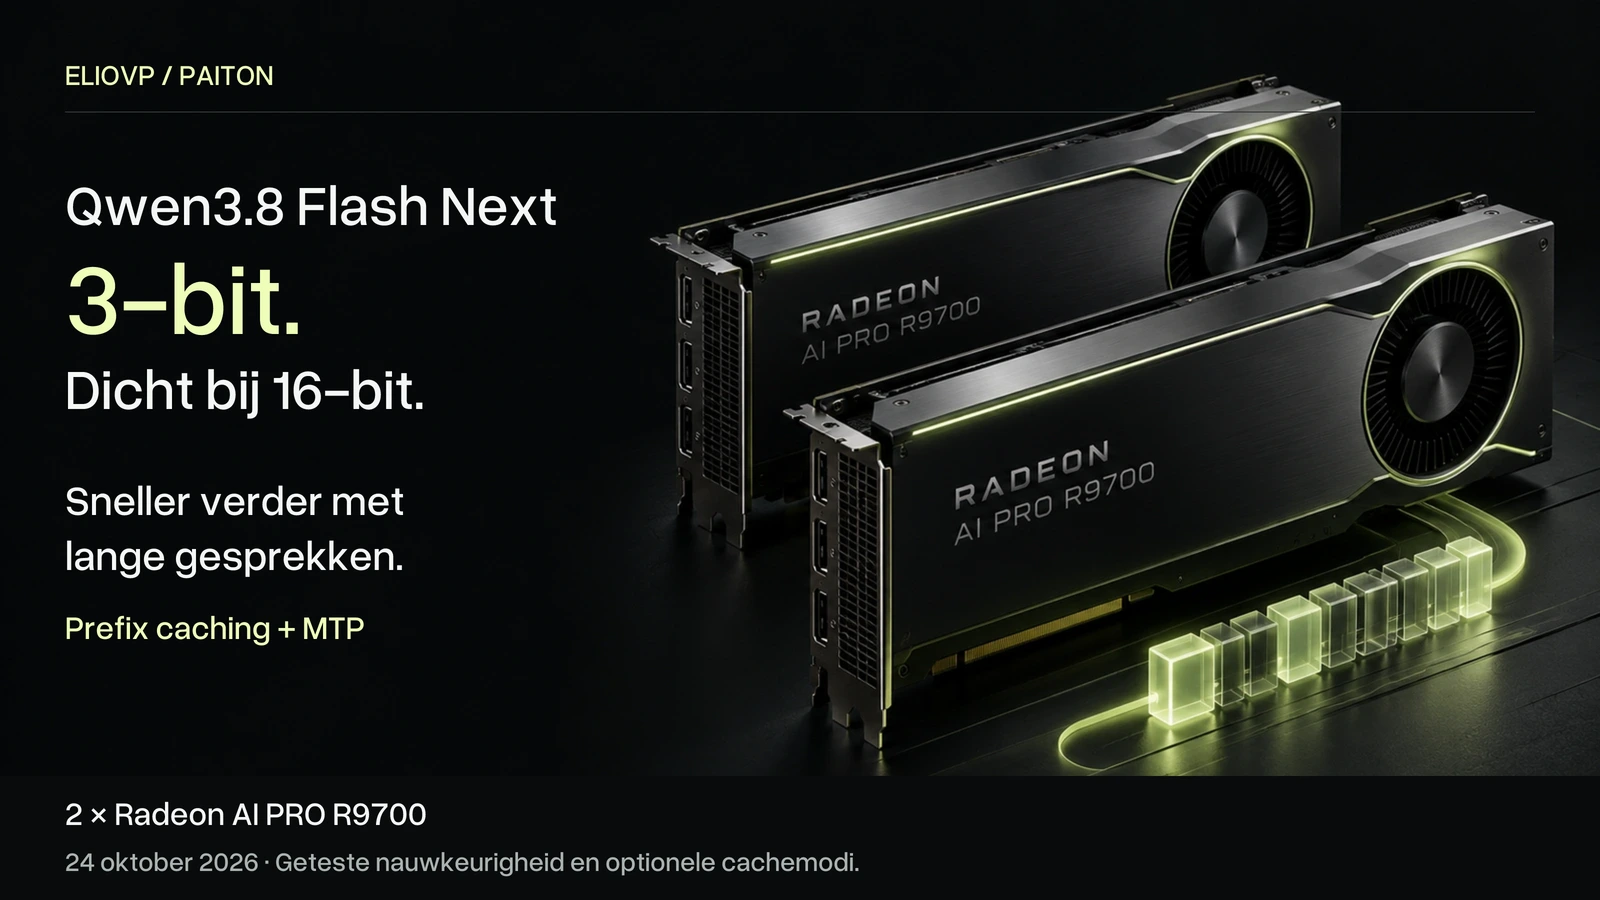
Qwen3.8 Flash Next: 3-bit dicht bij 16-bit nauwkeurigheid, met MTP-prefixcaching Paitons nieuwe 3-bit Qwen3.8-gewichten benaderen 16-bit taakscores op twee R9700-kaarten. Native MTP-prefixcaching hervat een prompt van 200K in 0,68 seconde. Resultaten, grenzen en installatie.
Door: ElioVP
24 oktober 2026
Paiton
Nvidia confirms the modular DC direction NVIDIA DSX POD brengt Vera Rubin AI-fabrieken naar modulaire datacenters. ElioVP bespreekt terreinvoorbereiding, koeling en de aanpak achter ModFlex.
Door: ElioVP
21 oktober 2026
Modular DC
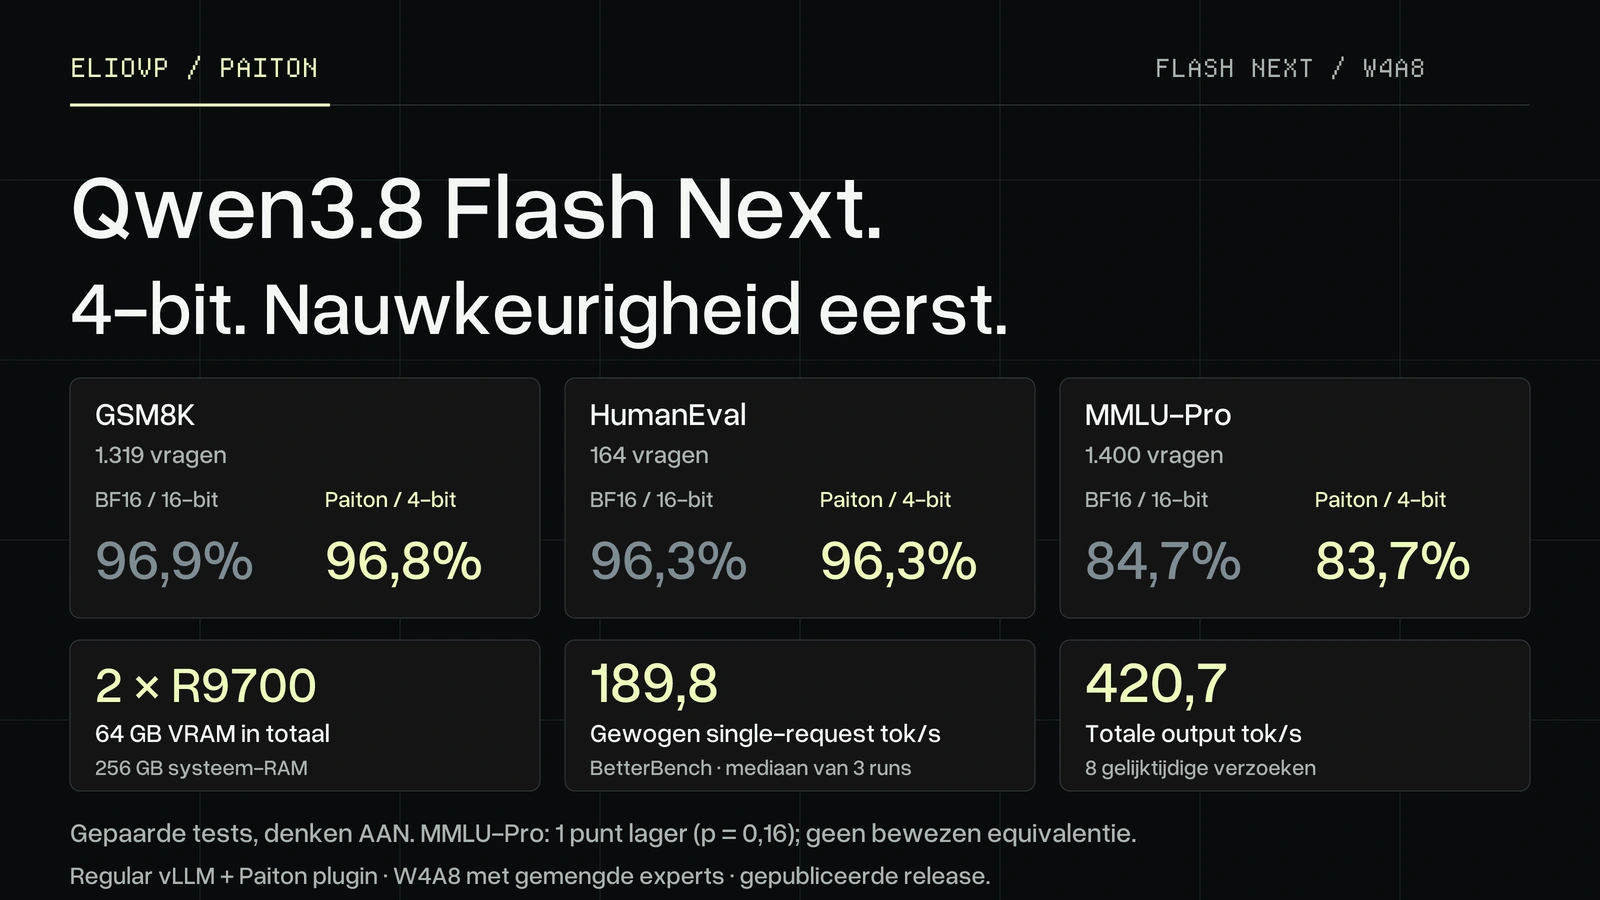
Qwen3.8 Flash Next in 4-bit op 2 × Radeon R9700: getest tegenover 16-bit Paiton draait Qwen3.8 Flash Next in 4-bit op twee R9700-kaarten: 96,8% GSM8K, 96,3% HumanEval, 189,8 tokens/s en een optionele RAM-prefixcache. Kwaliteit, snelheid en installatie.
Door: ElioVP
12 oktober 2026
Paiton
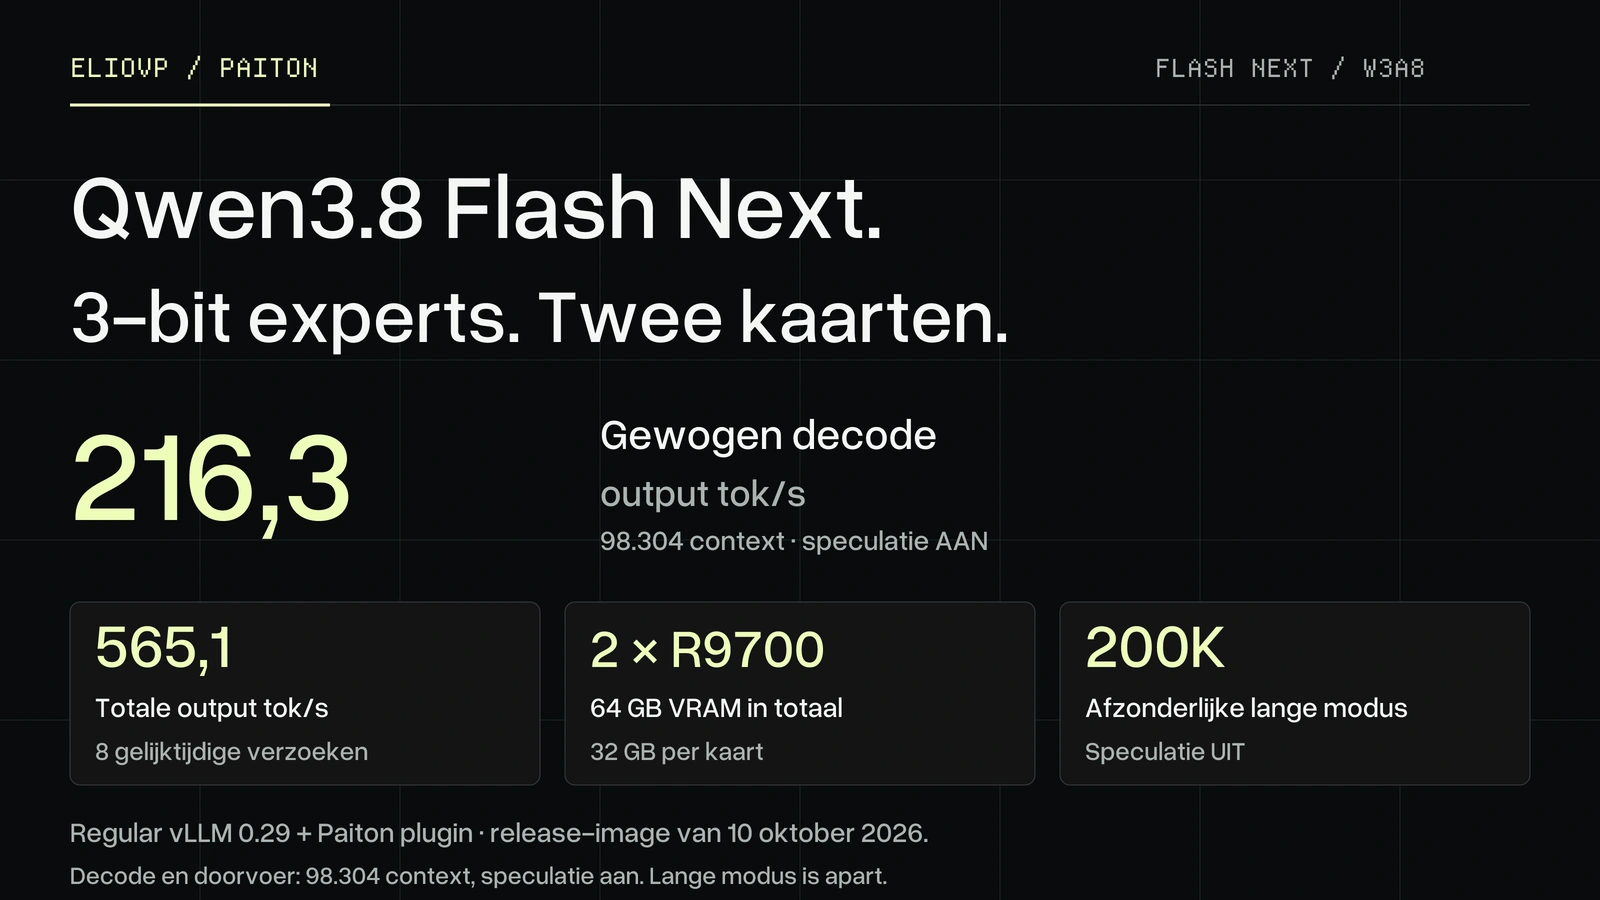
Qwen3.8 Flash Next op 2 × Radeon AI PRO R9700: 216 tokens/s, 200K-context Paiton draait Qwen3.8 Flash Next met 3-bit experts op twee R9700-kaarten: 216,3 tokens/s, 565,1 tokens/s samen en een aparte 200K-modus. Metingen, kwaliteit en installatie.
Door: ElioVP
10 oktober 2026
Paiton
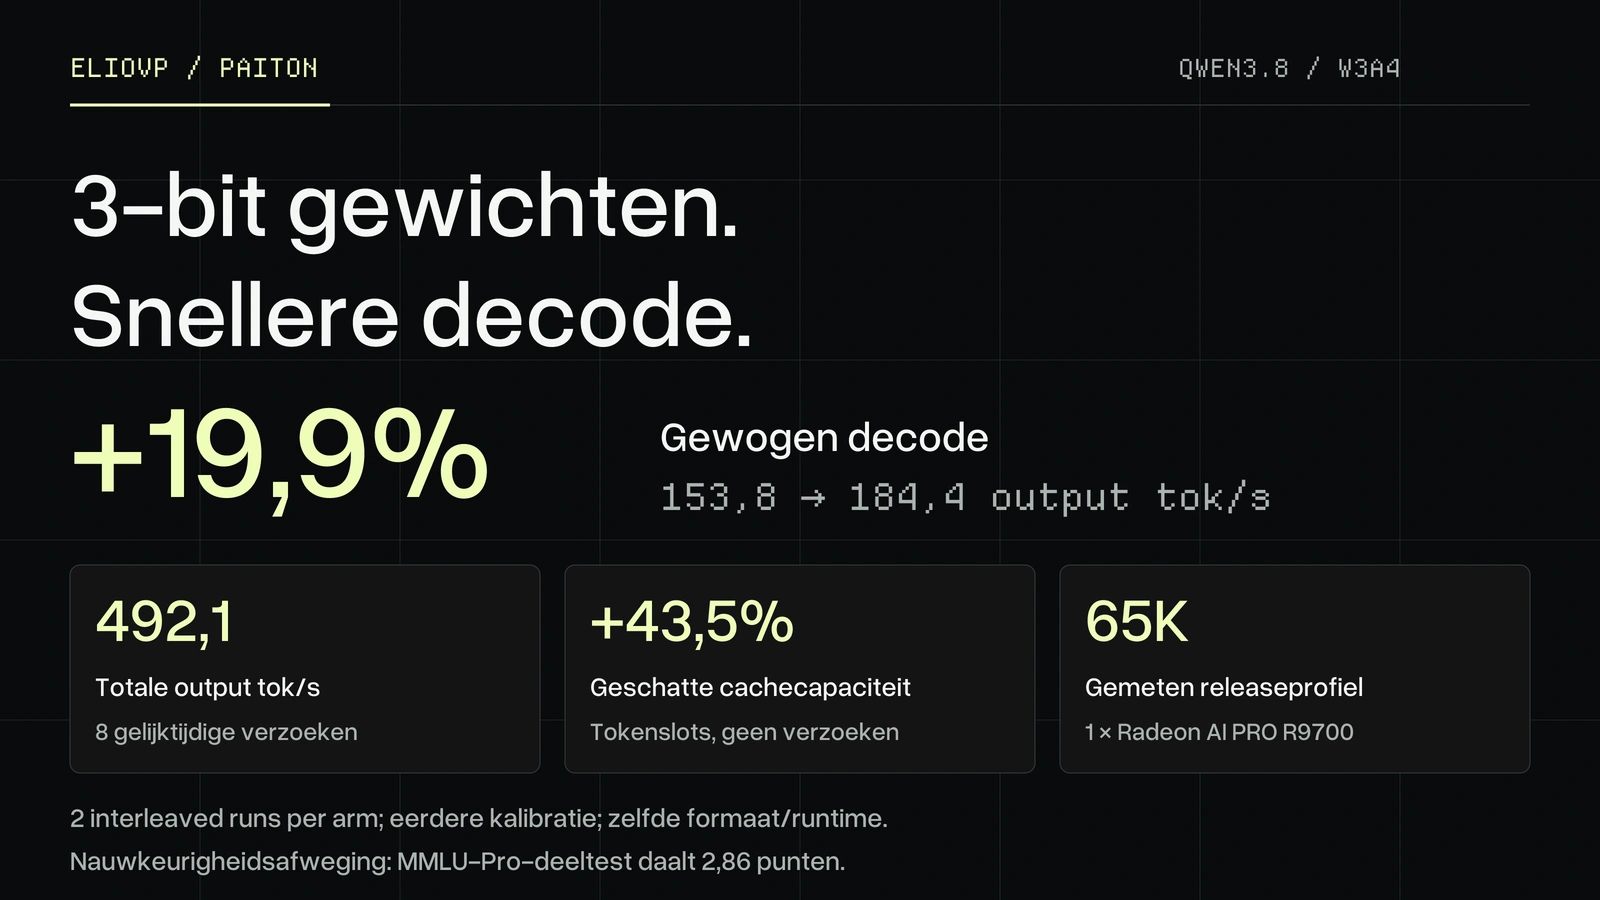
Qwen3.8 27B op 1 × Radeon AI PRO R9700: 3-bit gewichten, 20% snellere decode Qwen3.8 27B op één R9700: 19,9% snellere gewogen decode, een nieuwe 4-bit cache, 200K-context en optionele beeldinvoer. Metingen en Paiton-installatie.
Door: ElioVP
27 september 2026
Paiton