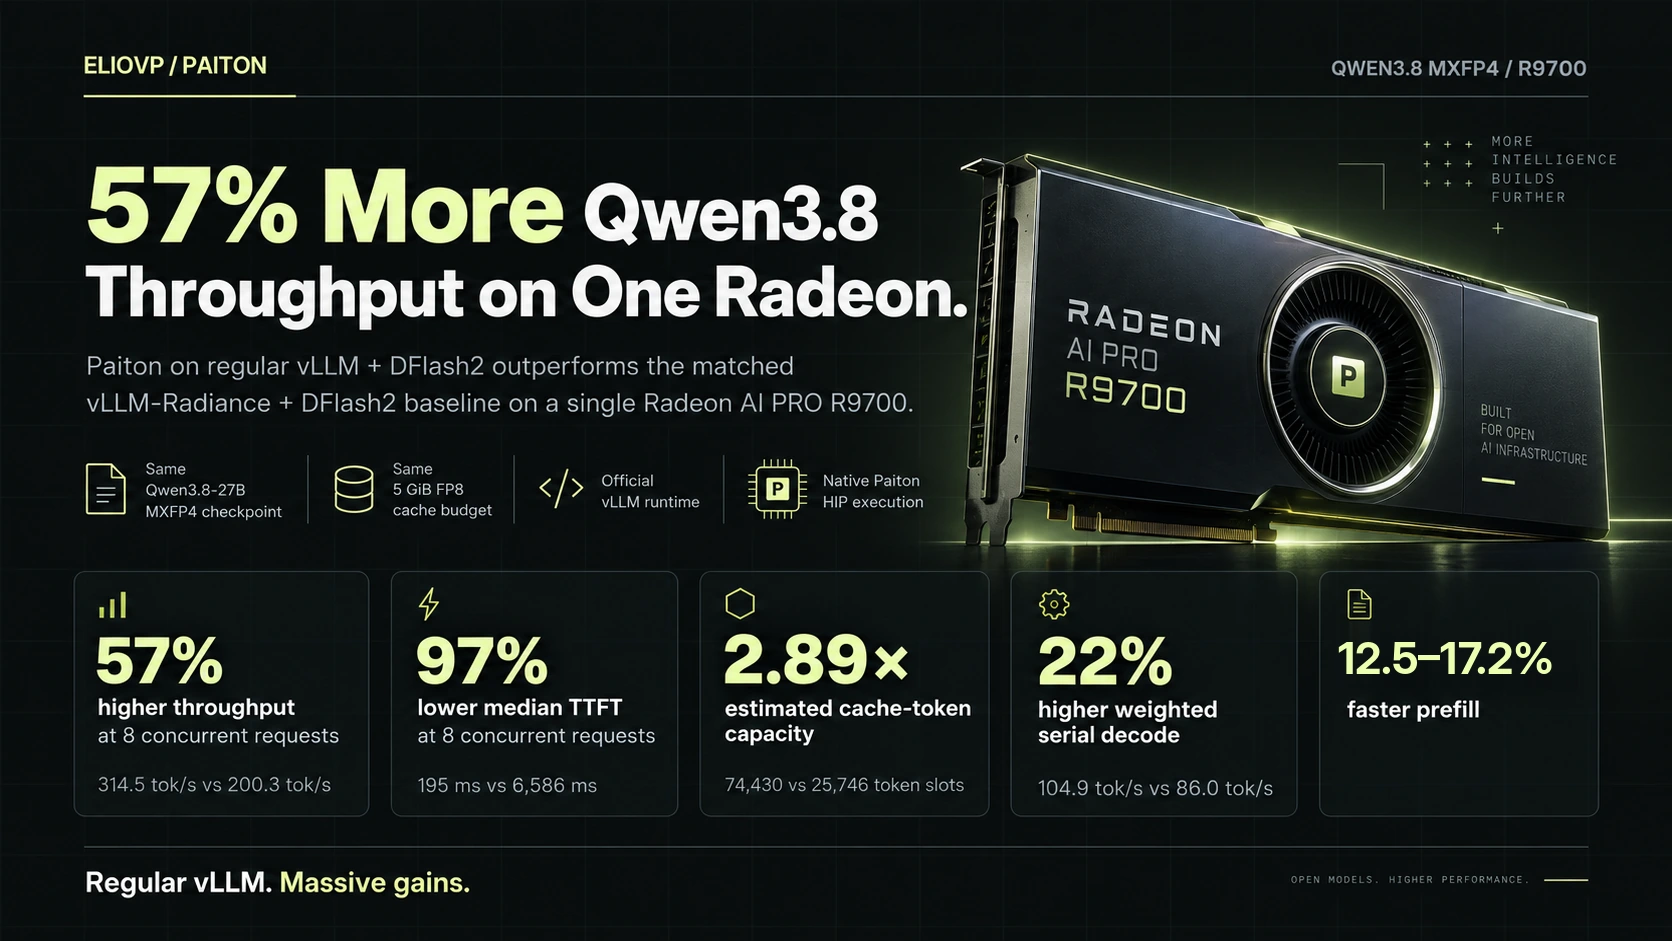
57% More Qwen3.8 Throughput on R9700 | PaitonPaiton delivers 57% more Qwen3.8 throughput, 97% lower median TTFT at eight concurrent requests and 2.89× estimated cache-token capacity on one R9700.
By: ElioVP
September 16, 2026
Paiton
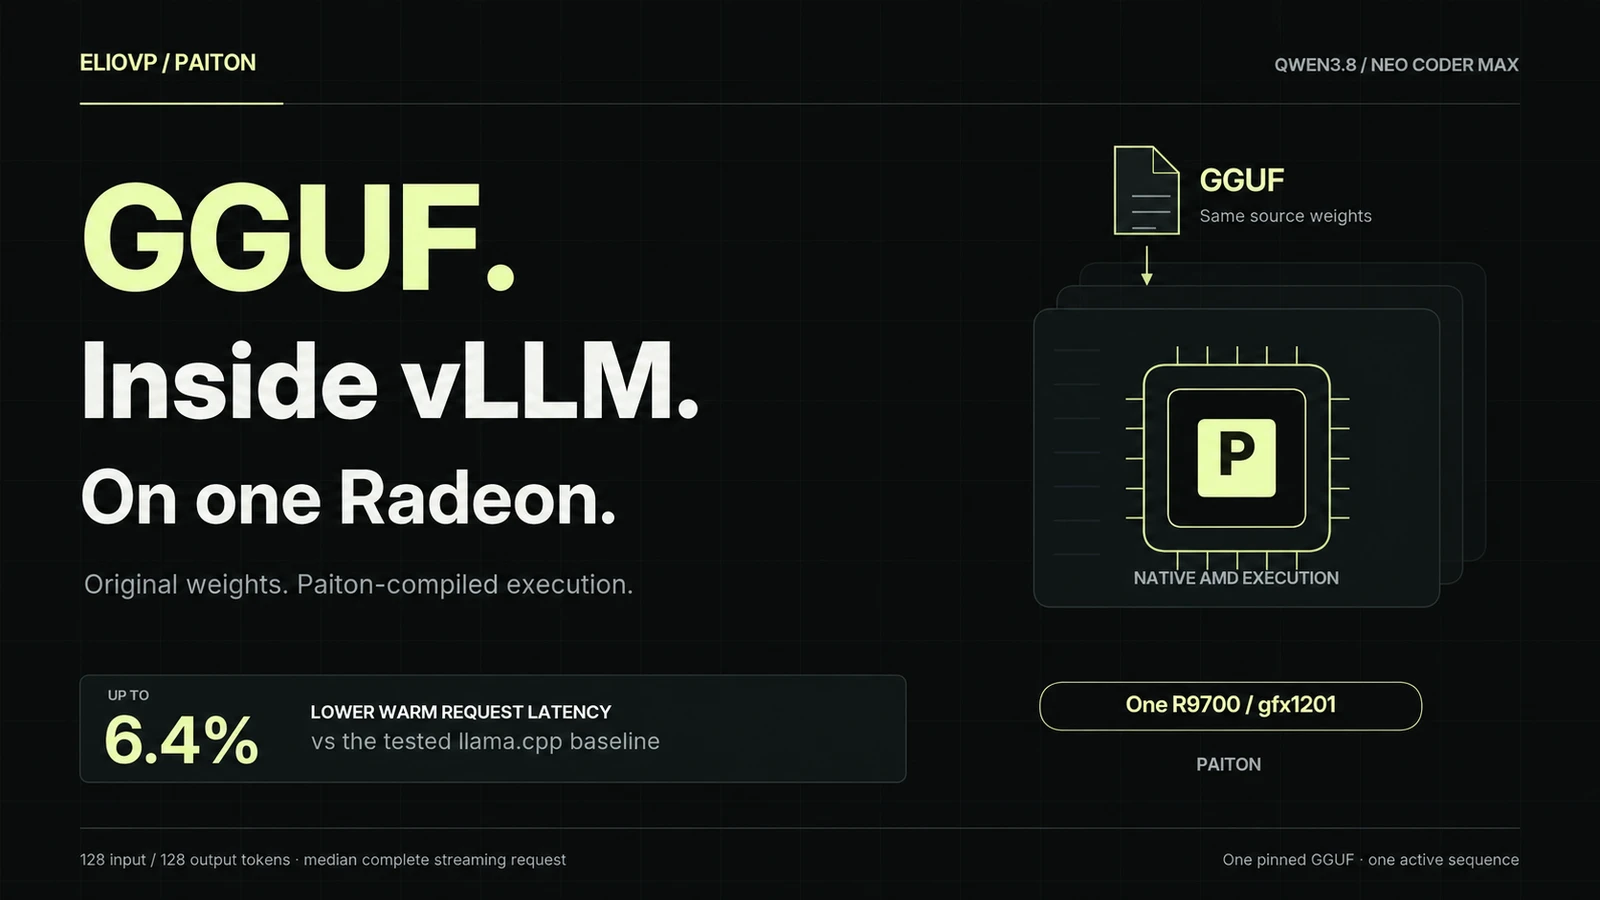
Qwen3.8 GGUF in vLLM: Faster Responses on One RadeonRun the original NEO CODER MAX GGUF in vLLM with Paiton on an R9700. Explore measured latency gains, image input and local deployment.
By: ElioVP
September 14, 2026
Paiton
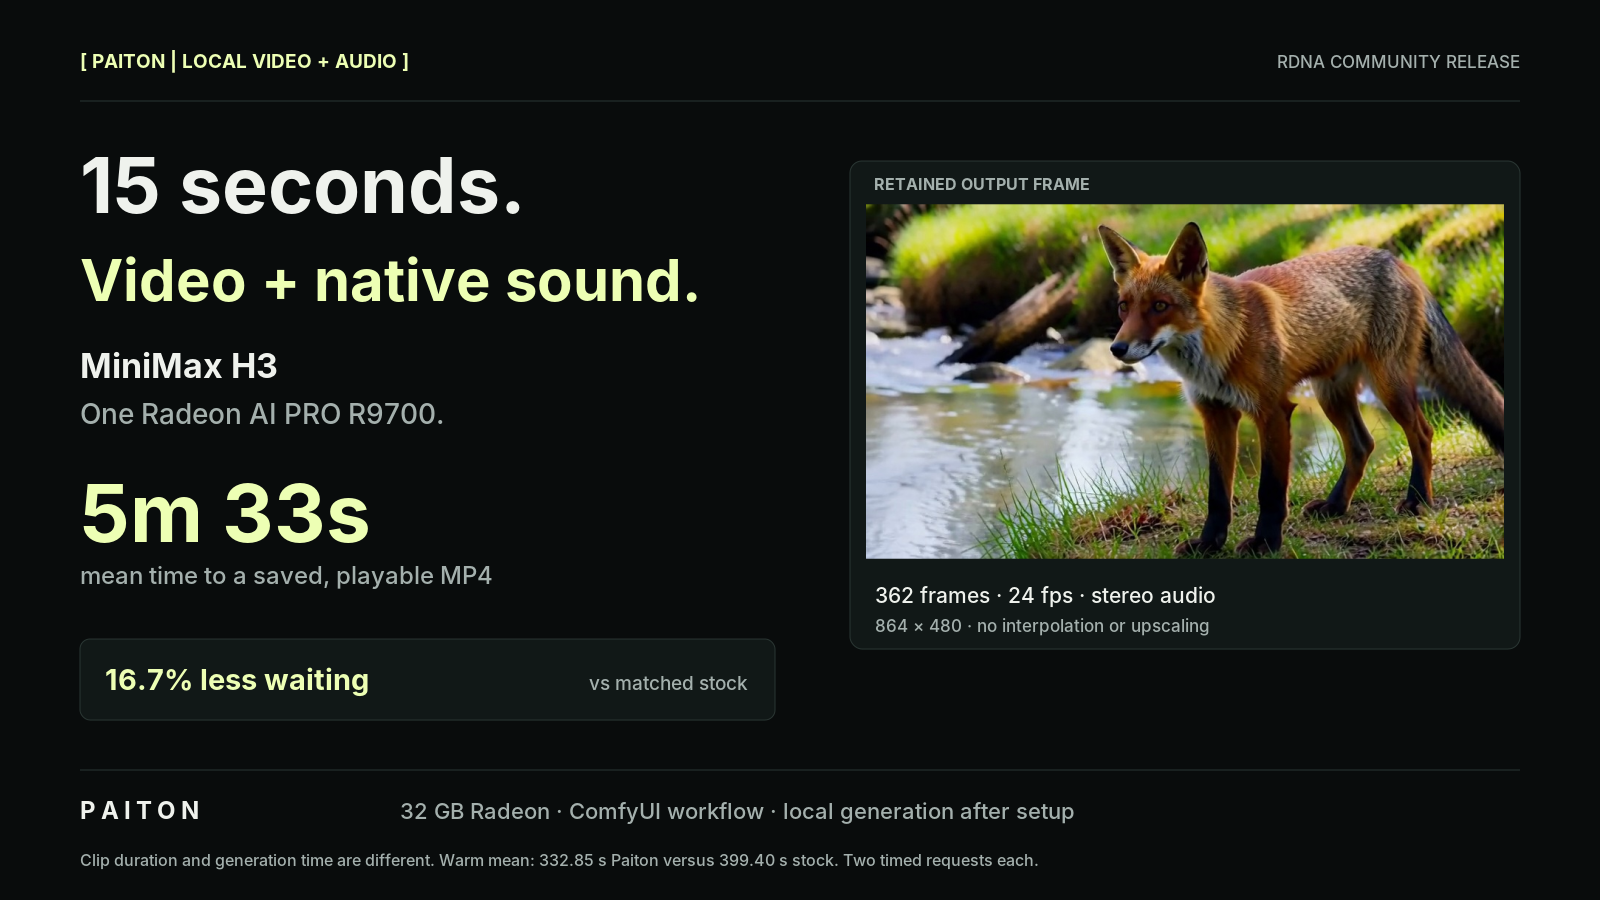
MiniMax H3 on Radeon: 15-Second Video With Native SoundPaiton generates a 15-second MiniMax H3 video with stereo audio on one Radeon AI PRO R9700 in 5m 33s, with 16.7% lower latency than matched stock.
By: ElioVP
September 9, 2026
Paiton
Local FLUX.2 klein on Radeon AI PRO R9700: Faster Image Generation with Less VRAMPaiton generates 1024×1024 FLUX.2 klein images in 1.054 seconds on an R9700: 16.2% lower warm latency and 33.4% lower peak Torch allocation.
By: ElioVP
September 7, 2026
Paiton
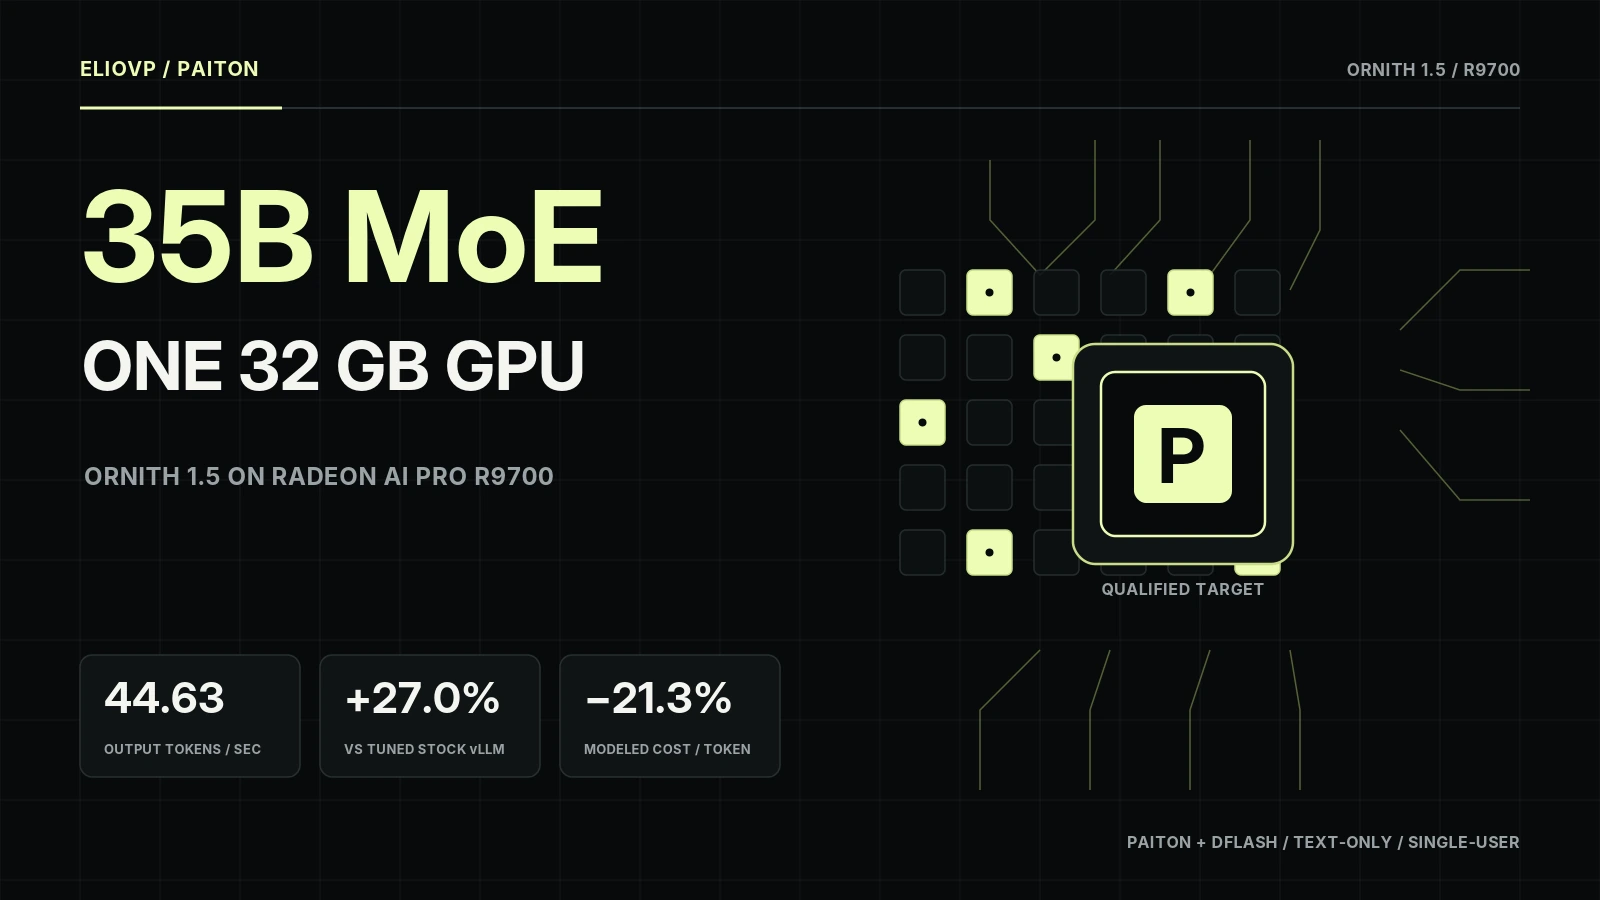
Ornith 1.5 at 44.6 tok/s on One Radeon AI PRO R9700Paiton serves Ornith 1.5 35B A3B at 44.63 output tok/s on one Radeon AI PRO R9700, 27% faster than tuned stock vLLM, with 21.3% lower modeled cost.
By: ElioVP
September 5, 2026
Paiton